A Jira migration is not an export-and-import job. A Jira site that has been running for a few years holds issues, comments, attachments, worklogs, sprints, links, custom fields, workflows, automations, filters and dashboards, plus all the habits your teams have built around them. Move it carelessly and you lose history people still rely on, or you recreate every bad configuration in a new tool.
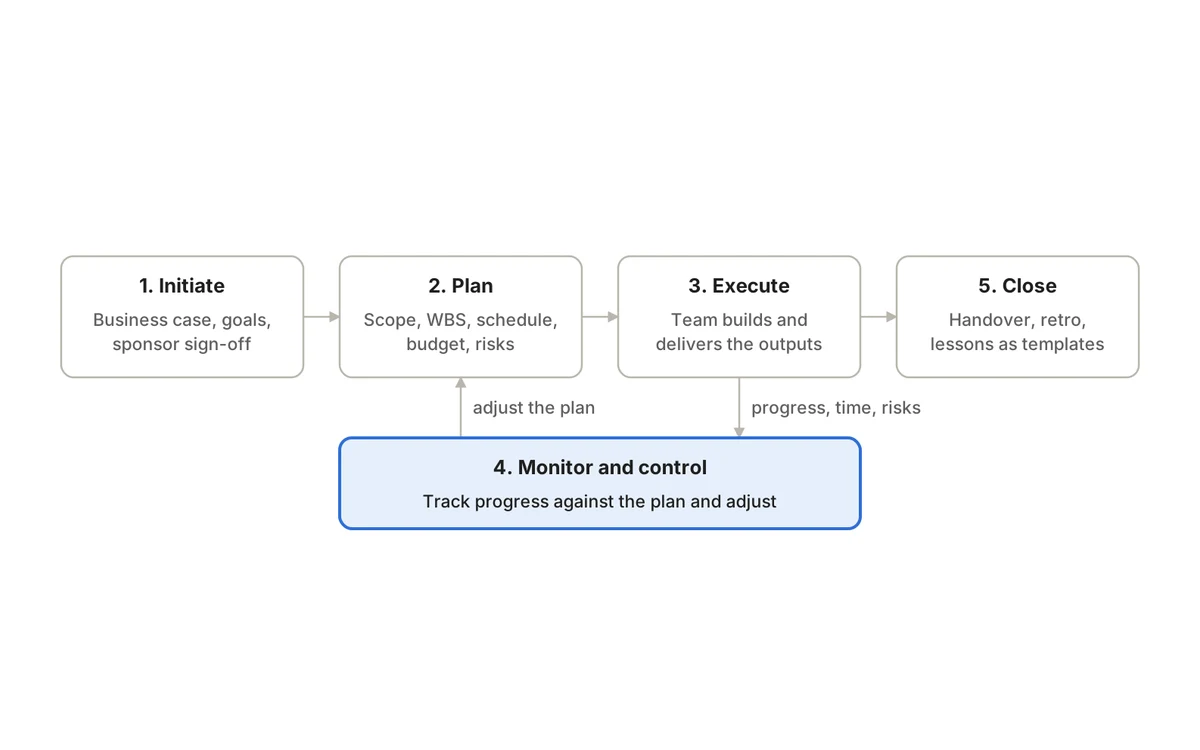
The safest approach is to run the migration as a small project with its own scope, owners, acceptance criteria and rollback plan. This Jira migration checklist walks through that project in eight stages, starting with what Atlassian itself lets you export, and ends with the mistakes that most often cause rework.
The Jira migration checklist at a glance
1. Define goal and scope
- Main output
- Signed-off scope: projects, history, dates
- Typical owner
- Sponsor and project lead
2. Take a backup and inventory
- Main output
- Archive copy plus inventory sheet
- Typical owner
- Jira admin
3. Clean up the source
- Main output
- Fewer projects, fields and statuses to move
- Typical owner
- Jira admin and team leads
4. Map fields, statuses and users
- Main output
- Approved mapping table
- Typical owner
- Team leads
5. Protect access and sensitive data
- Main output
- Permission plan, data-handling rules
- Typical owner
- Security or IT owner
6. Dry run on a sample project
- Main output
- Validation report, fixed mapping
- Typical owner
- Migration lead and pilot users
7. Cut over with a rollback plan
- Main output
- Go-live, source set to read-only
- Typical owner
- Migration lead
8. Validate and support
- Main output
- Owner sign-off, known-issues list
- Typical owner
- Project owners
| Stage | Main output | Typical owner |
|---|---|---|
| 1. Define goal and scope | Signed-off scope: projects, history, dates | Sponsor and project lead |
| 2. Take a backup and inventory | Archive copy plus inventory sheet | Jira admin |
| 3. Clean up the source | Fewer projects, fields and statuses to move | Jira admin and team leads |
| 4. Map fields, statuses and users | Approved mapping table | Team leads |
| 5. Protect access and sensitive data | Permission plan, data-handling rules | Security or IT owner |
| 6. Dry run on a sample project | Validation report, fixed mapping | Migration lead and pilot users |
| 7. Cut over with a rollback plan | Go-live, source set to read-only | Migration lead |
| 8. Validate and support | Owner sign-off, known-issues list | Project owners |
What Jira lets you export
Before planning anything, know which export routes exist on the Jira side. Atlassian documents three that matter for most migrations.
CSV export of work items
In Jira Cloud you can export work items from a project’s list view or from search, using the More actions menu and “Export CSV - all fields”. Atlassian’s guidance notes that each comment lands in its own Comment column in chronological order, and that Jira Cloud does not natively support downloading attachment files in bulk; a CSV carries attachment URLs instead. The file is UTF-8, so open it in a tool that reads UTF-8 correctly or special characters will be garbled.
Backup for cloud
Jira administrators can create a full backup from Settings, System, Backup manager, “Create backup for cloud”. According to Atlassian, it includes work items with system and custom fields, board and sprint data, users and group settings, comments, space configuration such as workflows, schemes and screens, Advanced Roadmaps data, and, if you tick the option, attachments, avatars and logos. Once unzipped, the database content sits in XML files with media in separate folders.
Just as important is what it leaves out. Atlassian lists automation flows, third-party apps and their data, some Jira Service Management features and certain Jira Product Discovery data as things that cannot be exported this way. If you include attachments you must allow 48 hours between backups, which matters when you plan several dry runs.
Data Center and Server XML backups
Self-hosted Jira has its own XML backup. Atlassian’s administration docs describe a backup service that by default writes a full XML export of the database every 12 hours, saved as a compressed archive in the shared home directory, and stress keeping a separate, up-to-date backup of that home directory because it holds runtime data that affects how Jira behaves and what it displays. With Data Center licenses scheduled to become read-only on March 28, 2029, per Atlassian’s September 2025 announcement, many self-hosted teams are planning this work now.
Whatever your destination, take one complete backup and store it somewhere you control before you change anything. It is your archive, your audit trail and your safety net.
1. Define the migration goal and scope
Write down why you are moving and what success means in measurable terms. A 40-person agency might want to replace Jira, a wiki and a timesheet app with one tool before a renewal date. An internal IT team might need to leave a self-hosted instance before its licenses lapse. The reason shapes every later decision.
- Which projects move, which are archived, and which are left behind.
- How much history must come across: all issues, or only open work and the last 12 months?
- Which data must be preserved for audit or contractual reasons even if nobody uses it daily.
- The target go-live date and any hard deadline such as a renewal.
- Who signs off that the migration is complete.
If you are still choosing a destination, settle that first; our guide to evaluating Jira alternatives covers requirements and pilots.
2. Inventory your Jira environment
Build a single inventory sheet. For each project, record its owner, last activity date, number of issues and attachments, and which of the following it uses:
- Issue types and hierarchy (epics, stories, tasks, subtasks, bugs).
- Statuses, workflows and transitions with conditions or validators.
- Custom fields, and which ones are actually populated.
- Boards, sprints, versions and components.
- Issue links (blocks, relates to, duplicates) and parent-child relationships.
- Worklogs, and whether hours live in native Jira worklogs or in a time-tracking app.
- Test cases or test runs held in a marketplace add-on.
- Automation rules, saved filters, dashboards and their subscribers.
- Integrations with source control, chat, CI or identity providers.
- Users, groups, project roles and permission schemes.
Then ask each team lead which filters, dashboards and reports they still open. Many will turn out to be abandoned, and not every historical configuration deserves to be recreated.
3. Clean up before you move
Migration is the cheapest moment to remove clutter. Close or archive projects with no activity in a year. Merge duplicate custom fields. Collapse statuses that mean the same thing (“In QA”, “Testing”, “Ready for test”). Resolve or bulk-close stale issues that nobody will ever pick up. Every field and status you remove is one less row in your mapping table and one less thing to validate.
4. Map fields, statuses and users
Create a mapping table from each source object to its destination equivalent, and get the owning team to approve it before any import. Resist forcing a one-to-one mapping where the new workflow is intentionally simpler.
Status: In Review, Code Review
- Destination
- In review
- Decision
- Merge into one status
Status: Ready for test, In QA
- Destination
- Testing
- Decision
- Merge; QA owns transitions
Custom field: Customer
- Destination
- Client field
- Decision
- Map directly
Custom field: Old priority (2019)
- Destination
- None
- Decision
- Archive in CSV, do not import
Story points
- Destination
- Story points
- Decision
- Map directly; check decimal values
User: departed employee
- Destination
- Inactive placeholder user
- Decision
- Keep history, no license
Component: Mobile, Web
- Destination
- Labels or areas
- Decision
- Map to the destination’s grouping
| Jira source | Destination | Decision |
|---|---|---|
| Status: In Review, Code Review | In review | Merge into one status |
| Status: Ready for test, In QA | Testing | Merge; QA owns transitions |
| Custom field: Customer | Client field | Map directly |
| Custom field: Old priority (2019) | None | Archive in CSV, do not import |
| Story points | Story points | Map directly; check decimal values |
| User: departed employee | Inactive placeholder user | Keep history, no license |
| Component: Mobile, Web | Labels or areas | Map to the destination’s grouping |
Pay special attention to users. Email addresses often differ between systems, contractors may have personal addresses, and departed staff still own historical work. Decide how each case is handled before the first dry run. It is also a good moment to tidy the backlog itself; our backlog management guide covers ranking and pruning.
5. Protect access and sensitive data
- Confirm who is allowed to export, hold, import and approve the data, and where export files are stored.
- Check whether comments or attachments contain personal data, credentials, customer files or anything subject to retention rules.
- Delete export files from laptops and shared drives once the migration is accepted.
- Recreate roles and permissions in the destination, then test them with representative accounts, such as a contractor who should see one project only, before opening access to everyone.
6. Run a dry run on a sample project
Pick a project that is representative rather than easy: one with several issue types, attachments, long comment threads, links, sprints and custom fields. Import it into a test space and check the results against the source.
Record counts
- How
- Compare issues per type and status in source and destination
Hierarchy
- How
- Spot-check epics, their stories and subtasks
Comments and authors
- How
- Open ten issues with long threads; check order and attribution
Attachments
- How
- Open files of different types and sizes
Dates and estimates
- How
- Created, resolved, due dates, story points
Worklogs
- How
- Compare total hours per user and per project
Sprints
- How
- Check sprint membership and completed versus open sprints
Everyday tasks
- How
- Ask two pilot users to do a normal day’s work
| Check | How |
|---|---|
| Record counts | Compare issues per type and status in source and destination |
| Hierarchy | Spot-check epics, their stories and subtasks |
| Comments and authors | Open ten issues with long threads; check order and attribution |
| Attachments | Open files of different types and sizes |
| Dates and estimates | Created, resolved, due dates, story points |
| Worklogs | Compare total hours per user and per project |
| Sprints | Check sprint membership and completed versus open sprints |
| Everyday tasks | Ask two pilot users to do a normal day’s work |
Log every defect, fix the mapping and run it again. Two or three rounds are normal, and the 48-hour gap between Jira backups that include attachments is worth building into the schedule.
7. Plan cutover and rollback
- 1.Agree a cutover window, ideally at a sprint boundary so no sprint is split across two tools.
- 2.Announce a change freeze, or define exactly how changes made during the migration will be reconciled.
- 3.Run the final import and the validation checks from the dry run.
- 4.Set the source Jira projects to read-only by adjusting permissions, rather than deleting anything.
- 5.Point integrations, bookmarks and team links to the new tool.
- 6.Name who can pause or roll back the cutover, and what would trigger that decision.
8. Validate and support after go-live
Ask each project owner to sign off on their data. Publish a short known-issues list and a support route. Expect questions in the first two weeks about missing filters, changed statuses or notifications, and keep the read-only source available until acceptance criteria have held for an agreed period. Document what moved and what was archived, so nobody has to rediscover it later; our project documentation guide has a simple structure for that record.
Things that rarely migrate cleanly
- Automation rules. Atlassian lists automation flows among data the cloud backup cannot export, and rules usually need rebuilding in the destination’s own automation engine anyway.
- Marketplace app data. Time-tracking, test-management and reporting apps keep some of their data outside core Jira, and the cloud backup does not export third-party app data. Plan a separate export for each app.
- Filters and dashboards. JQL queries and gadgets are specific to Jira; rebuild the handful that people actually use.
- Workflow logic. Conditions, validators and post-functions rarely have exact equivalents. Rebuild the intent, not the mechanics.
- Full change history. Field-by-field history is often summarized or dropped. If you need it for audit, keep the backup archive.
Common Jira migration mistakes
- Migrating everything because deciding is hard, then validating far more data than anyone needs.
- Skipping the dry run, or running it on the simplest project.
- Leaving user mapping until the end, so work lands on the wrong people or on nobody.
- Switching mid-sprint and splitting the team’s work across two systems.
- Deleting or decommissioning the source before owners sign off.
- Forgetting the costs on the other side, such as add-on renewals that auto-renew; our tool sprawl cost guide has a checklist of subscriptions to retire.
Migrating from Jira to QuikProjects
QuikProjects has a built-in Jira importer that brings across issues, epics, subtasks, sprints, story points, comments, worklogs, attachments and users, and it runs a dry run first so you can review results before committing. Teams coming from ClickUp, Asana, monday.com, Linear, Zoho or spreadsheets can import their backlog via CSV, and the importer flags anything it could not match.
Objects outside that list, such as automation rules, dashboards, workflow logic and custom fields, should be checked in your dry run and rebuilt where needed, which is good practice with any destination. You can keep Jira running while you try QuikProjects; Premium and Pro start with a 14-day trial with no credit card, and the Free plan covers up to 10 users. For a broader view of how the two products differ, read our QuikProjects vs Jira comparison, and for wider context on running projects well, the complete guide to project management.
Frequently asked questions
How long does a Jira migration take?
It depends far more on scope and cleanup than on data volume. A single team with a tidy project can move within days; a multi-team site with years of custom configuration, marketplace apps and audit requirements needs several weeks of inventory, mapping and dry runs. Plan the dry-run rounds first and the timeline follows.
Do worklogs and time-tracking data transfer?
Native Jira worklogs are part of the issue data. Hours or attributes stored by a time-tracking app may not be, because Atlassian’s cloud backup does not export third-party app data. Check where your time data actually lives, and compare totals per user and project after each dry run.
Should we migrate closed issues?
Migrate what people search for. Many teams bring open work plus a recent window of closed issues, and keep older history in the archived backup and a CSV export. If you have audit or contractual obligations, agree the retention approach with whoever owns them.
Can we keep Jira as a read-only archive?
Yes, by restricting permissions so users can browse but not edit, for as long as you keep the subscription. Self-hosted licenses become read-only at Data Center end of life anyway. Either way, keep your own backup so the archive does not depend on a license.
A good migration protects the information people need and leaves the clutter behind. Back up first, map deliberately, test on real data and keep a way back. When you are ready to try it with your own projects, start QuikProjects free for up to 10 users and run the Jira importer’s dry run before you commit.
Sources
See it running on your business.
A walkthrough built around how your team works today.